Insights
By the Time You Price It, the Meter Is Already Chosen
September 8, 2026 · Ameet Kulkarni
Most companies believe they choose their pricing meter. In practice, by the time the pricing conversation happens, the meter has usually been decided by something else: the architecture, the telemetry built around it, the billing system, or simply what the rest of the company already knows how to charge for. The pricing team may still have a choice, just a much smaller one than everyone in the room thinks.
Google’s change to Gemini Notebook on September 2 is a good example.
Notebook inherited a familiar meter
On September 2, Google moved Notebook, the product most people still call NotebookLM, onto usage limits based on chat length, the number of sources, and the features you use. At one level those limits make sense. More sources need more processing, longer conversations accumulate context, and some features presumably cost more compute than others. Heavy users cost more to serve than light users, and a product needs some way to tell them apart.
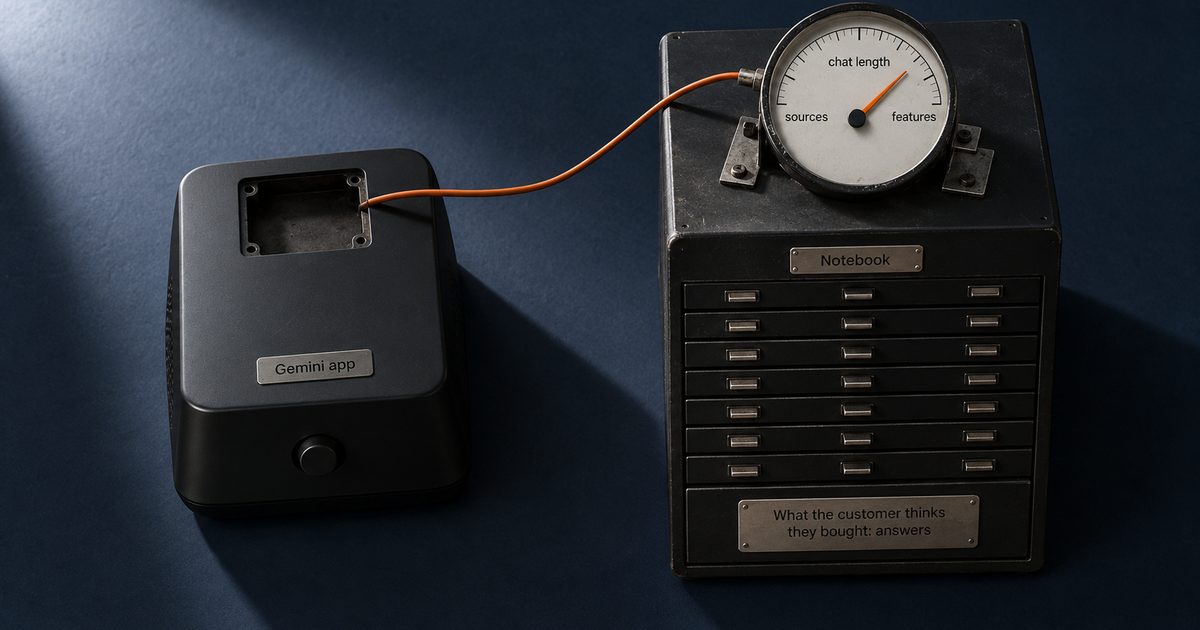
The interesting part is not that Google introduced limits. It is what Google chose to count. The meter looks a lot like the one the Gemini app has carried since May: how much you put into the system, how long you interact with it, and which expensive capabilities you use.
Notebook is a different product. A Gemini conversation is mostly transactional, in that I ask something, the model does work, and I get an answer. Notebook has another layer of value, because I give it a body of material and expect that material to become useful over time. The sources are not inputs to one transaction. They are closer to an asset I expect the product to understand and keep helping me use.
So when I ask a fifth question about the same collection of documents, the product has delivered more value to me, but I have not added any underlying knowledge. The system counts another interaction, and the customer experiences continued use of something they already built. That distinction matters.
I do not know Google’s internal architecture or cost curve, and anyone outside Google claiming to know exactly why these limits were chosen is guessing. The limits may map very closely to Google’s marginal costs, and that is precisely what makes the example useful. A meter can make perfect sense to the system and still be an imperfect picture of what the customer thinks they are buying.
There are really three meters
When I work on AI monetization, I find it useful to separate three things that usually get collapsed into one. I have started calling them the three meters, because each one is a real instrument measuring a real thing, and the trouble starts when a company reads one while believing it is reading another.
The cost meter is whatever actually makes the product more expensive to run: tokens processed, model calls, context reconstructed, images generated, searches executed, whichever unit carries the bill. The usage meter is what the product can reliably observe and count, such as messages, documents, sources, seats, minutes, credits, or tasks. The value meter is what the customer believes they are paying to get, which is answers, completed work, an analyzed knowledge base, faster decisions, hours saved, or revenue generated.
In a well-designed pricing model the three are related, and they rarely match perfectly. That gap is where a lot of AI pricing problems begin. A company may want to price around value, but value is hard to observe, cost is easier, and usage is easier still, so the measurable thing becomes the billable thing and, eventually, the billable thing starts looking inevitable.
Meters are inherited, not designed
Companies tend to imagine pricing development in one order: work out what customers value, choose the pricing model that fits, define the meter, and then build the systems required to support it.
Customer value → pricing model → meter → implementation
That is often not what happens. Engineering makes a set of reasonable decisions about how the product works, instrumentation gets built around those decisions, finance learns which costs it can attribute, and billing learns which events it can count. Then, months later, someone starts the pricing project.
Architecture → measurable unit → billing capability → pricing options
At that point you can still propose a different meter. But “charge for X instead” may now mean changing telemetry, rebuilding entitlement logic, modifying billing infrastructure, creating new reporting, and possibly changing the product architecture itself. The theoretically better pricing model suddenly has an engineering estimate attached to it, while the existing meter already works.
So the usual outcome is not a decision to keep the meter. It is a year of nobody proposing the alternative, followed by a pricing meeting where the options are already narrow and everyone agrees the narrow one is sensible.
This gets worse with AI
Traditional software hid this problem reasonably well, because marginal serving costs were often small. If one customer created ten dashboards and another created a hundred, the difference rarely mattered economically, and you could afford some looseness between usage and cost.
AI changes that, because every major capability can carry its own variable cost. One feature grows with tokens, another with documents indexed, another with searches, another with images, another with session length, another with the number of agents running in the background. I wrote earlier about this as the AI cost stack: individually reasonable features accumulating into a cost structure nobody designed as a whole.
Pricing has the same problem. Each architectural decision creates a candidate meter, and over time those meters become operational facts. Then the business discovers it is not deciding how it wants to charge. It is deciding which of the things it already measures it can plausibly charge for.
The right time to discuss the meter is earlier
This does not mean product teams should design architecture around pricing. It means the monetization conversation needs to happen while the architecture still has options. For every expensive AI capability, I would want three answers before the design hardens:
| Question | |
|---|---|
| Cost | What actually makes our cost increase? |
| Usage | What can our systems reliably count? |
| Value | What does the customer think they are paying us for? |
If the same answer appears three times, pricing will probably be straightforward. If the answers differ, pay attention. That does not automatically mean the architecture is wrong, because charging on a usage proxy is sometimes exactly the right decision, and a perfect value metric that customers cannot predict or the company cannot meter is not much use to anyone. But the mismatch should be deliberate.
Once the architecture ships, instrumentation gets built, billing gets wired up, and customers get used to the product, changing the meter gets progressively more expensive. The pricing decision has not disappeared. The range of feasible decisions has.
That is why I increasingly think pricing architecture belongs much earlier in product development than most companies put it. Not because product managers should be setting prices before they build the product, but because they should understand which commercial choices their technical decisions are quietly removing.
I keep a short self-check I work through with companies on this, twelve questions in about five minutes, and the three above are the ones that do most of the work. If it would be useful, email me and I will send it over. Nothing is attached to it.
The meter is downstream of the architecture. By the time you can read it, you have been paying for it for a while.